October 2026
50 videos summarized
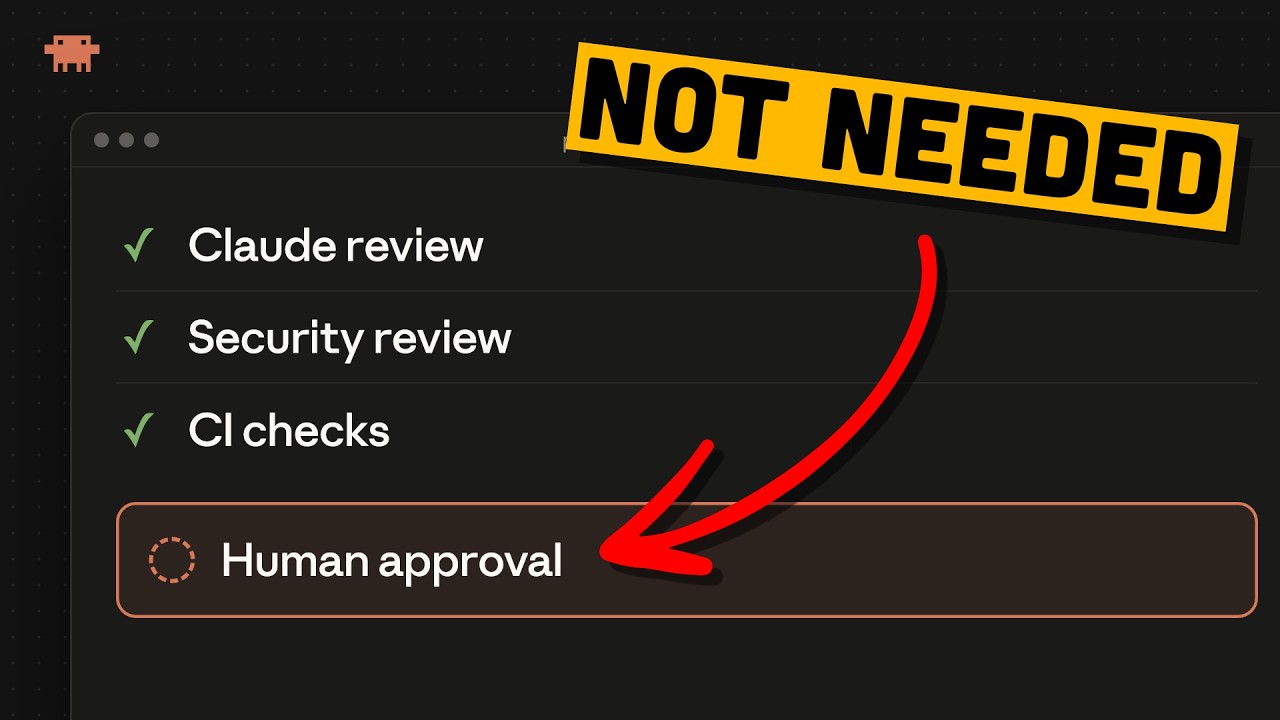
Anthropic says Claude now writes ~90% of Claude Code's own code, so they've shifted from "did a human read this?" to layered automated checks plus risk-tiered human review. The flow stacks self-checks, multi-agent bug review with voting, a security pass, CI, and a classifier that decides whether 0, 1, or 2 humans must approve. They keep the reviewer honest with daily evals built from real incident bugs, and cap review rounds after agent-vs-agent loops ran a PR through 50+ cycles. The video closes by poking at the headline stats: a 40% drop in revert rate alongside doubled PR volume still means roughly 20% more reverts overall.
Read the full summary
Jake Van Clief argues that most people don't need to build custom AI agents — they need well-organized folders of markdown files describing who they are, how they like things built, and who their clients/investors are. He contrasts the old approach (databases behind APIs, custom Python connectors, per-task tools, one agent per output format) with giving a single model a minimal "harness" of read/write/search tools plus a readable folder tree, so adding a new capability means adding a folder instead of building a new agent. The second half of the video traces computing history — the Jacquard loom, Ada Lovelace, Descartes, Turing, Claude Shannon, Grace Hopper, compilers, C and Python — to argue that natural language is simply the latest layer of abstraction over machine code, and that structuring your intent in folders is the current step in that lineage.
Read the full summary
The Only SaaS Moats Left in 2026
Rob Walling's MicroConf Europe talk argues that AI isn't ending SaaS, but it is quietly dismantling most of the moats founders relied on. He lays out ten ways AI can attack a SaaS business — six supply-side (customers, competitors, open source, platforms, agencies, the models themselves) and four demand-side (customers going out of business, seat contraction, the managed workflow disappearing, humans being replaced by agents) — and estimates 10–20% of SaaS companies will decline or go to zero. He then names eight moats he thinks still hold, each with a big-name and a small bootstrapped example, plus the question you should ask to test whether you have it.
Read the full summary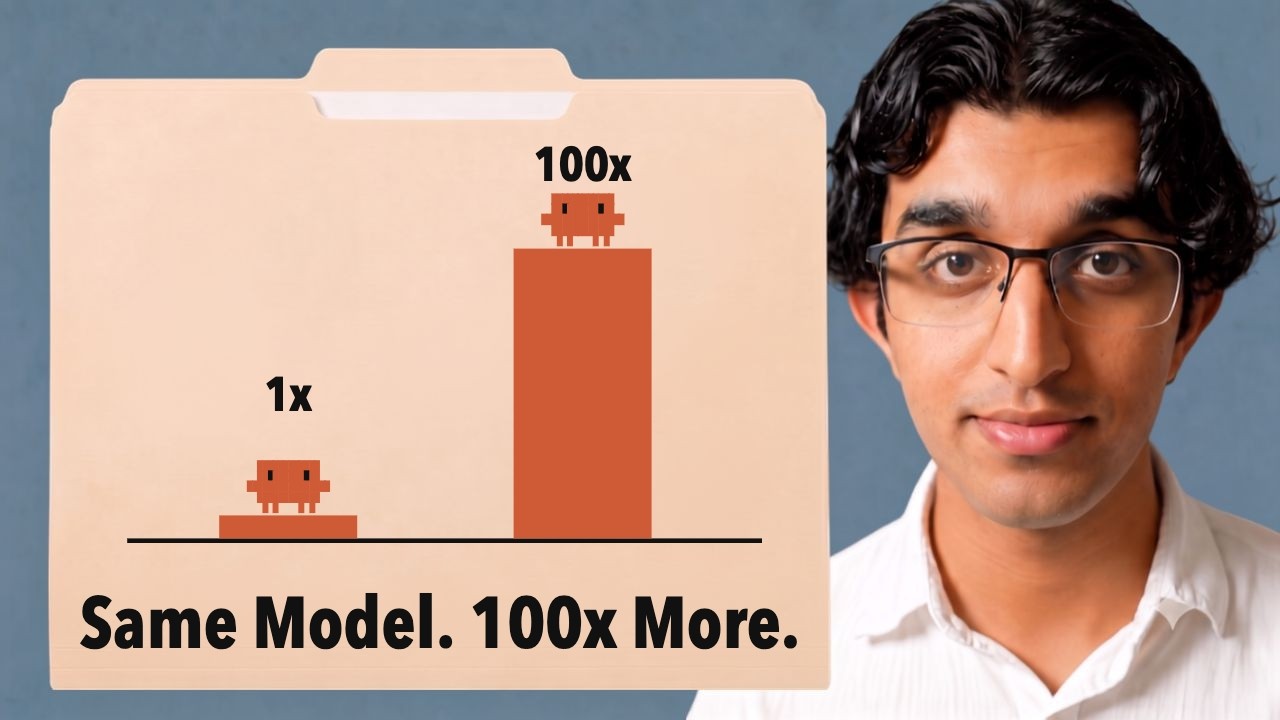
Ray Amjad walks through Felix's Anthropic essay "How to Be More Ambitious," which splits ambition with AI agents into four types: speed, altitude, depth, and range. He skips speed as the thing everyone already does, and spends the video showing concrete Claude Code and Slack-agent setups for the other three: prompting for outcomes instead of tasks, insisting the model use the actual tools an expert would use, and borrowing solutions from unrelated professions. The through-line is that the bottleneck is no longer the model but the ambition of the prompt and the tooling/access you give the agent.
Read the full summary
Pstack Is Agent Overkill. Use It Anyway!
Rob Shocks walks through Pstack, a skill/playbook bundle from Lauren Tan (React core team, ex-Netflix, SpaceX, now Cursor) that packages a senior engineer's workflow into 20+ agent skills routed by a "potato mode" dispatcher. He uses it to one-shot a skill manager app called Molten Base, then breaks down the standout skills (arena, swarm, why, recall, interrogate, create/maintain verification, onslaught, brawl) and the underlying principles. Verdict: it roughly doubled build time and burns far more tokens than a plain agent run, but produced a noticeably more hardened app, so it's worth using selectively rather than on every project.
Read the full summary
Agentic Coding Scam
Earl Brandt of Kira argues the industry's latest pitch — that the real value of AI coding lies in increasingly elaborate agent "harnesses" — doesn't hold up. He walks through a recent EPFL/Apple paper where a bare-bones agent with just a file system and three tools beat sophisticated multi-agent scaffolding across every frontier model tested, with delegation and sub-agent setups actually making results worse. The second half is an interview with a developer, Marcos, who uses Brooks' "No Silver Bullet," Gall's law and Jevons paradox to argue that AI shifts where engineers work rather than eliminating them.
Read the full summary
Eric walks through an open-sourced "software factory" — a set of Claude-style agent skills that pull issues from telemetry tools (Sentry, PostHog), turn them into GitHub tickets, and run them through a builder → QA → reviewer loop that mimics a real dev team. Each specialist agent chains curated skills: Ponytail for complexity reduction, Context7 for library docs, MapPoke for implementation, plus dedicated QA and review flows, with every agent comment logged on the GitHub issue. The setup is meant to be model- and harness-agnostic (Claude Code, Codex, etc.) and installable in about three steps.
Read the full summary
Claude Code Projects is a beta feature (waitlist, now effectively open) that puts a Claude orchestrator in Anthropic's cloud, where it spawns and manages persistent full Claude sessions called threads. Unlike sub-agents, each thread keeps its own context window, opens its own pull requests, can be messaged directly, and keeps running when your machine is off — and it bills against your Max subscription usage rather than API credits. The video walks through the settings (coordinator vs thread models, memory, GitHub repo, cloud environments, secrets, local folder access) and a 25-minute demo where one prompt split into five parallel threads that built an "AI Creator Radar" dashboard.
Read the full summary
Two bets on AI are running in opposite directions: that AI makes software worthless, and that AI companies won't earn enough to repay their debts. The first bet looks weak — the viral "free Photoshop" built with AI covers only about a third of professional work by its own roadmap, and Adobe just posted a record quarter even as its stock fell ~30%. The second bet has real evidence behind it: AI borrowing collapsed from a record $113B in June to $23B in September while the cost of insuring Oracle, CoreWeave and even Big Tech debt hit records. The video's conclusion is that AI can make code cheap to copy without making anyone rich — the value may be leaking out to users rather than landing with model makers or lenders.
Read the full summary
A tour of the creator's complete daily terminal setup, layer by layer: Ghostty as the terminal emulator, tmux (with his own SessionX and Floats plugins) for multiplexing, Workmux for managing Git worktrees, and Pi as his coding agent. He also announces he has abandoned Nushell and returned to zsh/POSIX after a year of advocating for it. The rest covers zoxide, Atuin, fzf, Starship, Neovim, Superfile, Television and Mise, all of which live in his public dotfiles repo.
Read the full summary
Bigger context windows don't make agents more reliable a study of 18 frontier models found all of them degraded as context grew, a phenomenon called "context rot." The video breaks down four ways an agent's context window goes bad (poisoning, distraction, confusion, clash) using a running example of an agent migrating a codebase to a new database driver. Each fix validate, compact, curate, prune works by deliberately throwing information away.
Read the full summary
A walkthrough of P-Stack, an open-source repo of AI coding skills, workflows, and principles published by Lauren Tan (Cursor, ex-Meta/React team). The reviewer maps her skills onto a six-stage AI software development lifecycle — planning, design, building, testing, deployment, maintaining — and notes the defining difference from other skill sets he's reviewed: P-Stack fans work out across multiple models and agents instead of relying on a single model. He concludes that the planning skills are weak for greenfield solo building, but the design fan-out, the 'no comments' rule, 'attack the premise,' and the type-system principles are worth stealing.
Read the full summary
Matt Pocock, a self-taught developer who says he stopped writing code by hand around the release of Opus 4.5 in December 2025, argues the highest-leverage skill in the AI era is communication: being able to surface your unknown unknowns and tell an agent exactly what you care about. He claims the environment agents work in (a clean, testable, verifiable code base) matters far more than which model or harness you pick, and tells the story of abandoning spec-driven development after months of watching his code quality degrade. His practical advice: climb a "trust ladder" slowly, give agents your boring work rather than your most ambitious tasks, and run models at lower effort levels than most people do.
Read the full summary
IndyDevDan walks through Pi durable, a new release from the Pi coding agent maintainers that detaches agents from the client so they survive crashes, restarts and disconnects while keeping session, shared application state, tasks and tools. He demos a 'proactive' on-call agent that a Jev classifier triggers off a live event stream: it detects a production bug, investigates, writes a fix and waits for his approval, all for pennies. The rest of the video tours the durable feature set (background compaction, shared JSON app state across sessions, phased durable jobs, hot-swappable tools and extensions, forking) and argues that owning a controllable, extensible harness is the key move for agentic engineers.
Read the full summary
We ran some benchmarks
A hands-on benchmark of the new hosted "system one" classification model (transcribed as "Jeff"/"Jev") against classic few-shot machine learning. On AG News, TREC, 20 Newsgroups and Clinc-150, it beats SetFit trained on eight examples per class by roughly 9 points and costs about a penny and a half per validation run, but open Qwen models wrapped in a "Decider"-style token-matching setup get competitive or better locally. The conclusion: don't think of it as a classification model — it's a classifier plus a little bit of quick reasoning, and its best use may be as a labeler that bootstraps or audits your own models.
Read the full summary
Vercel CEO Guillermo Rauch walks through how he actually works with coding agents: a minimal CLI harness (FX) aliased into shell shortcuts, agents used for research and "agentic inquiry" rather than line-by-line code review, and a company policy of trying every model rather than standardizing on one. He argues the real differentiator is iteration velocity (speed in a direction) and latency from customer signal to shipped fix, not PR counts or token spend. A large chunk of the conversation is about security: he claims human-written code hides an immeasurable backlog of latent vulnerabilities that agents can now find cheaply, pushes memory-safe rewrites and cloud sandboxes, and criticizes OpenAI/Anthropic for not releasing full agent traces after the Hugging Face incident.
Read the full summary
Dex (Human Layer) and Aaron (CTO of Boundary/BAML) walk through a pipeline that mines a team's coding-agent sessions and turns them into proposed CLAUDE.md entries, rules, and a report on what agents keep getting stuck on. The naive version (strip tool calls, dump user/assistant messages into one structured-output call) was directionally right but bad and expensive; the rebuilt BAML pipeline splits into three sub-flows — facts agents discovered, corrections humans made, and questions agents keep re-researching — with cheap classifier pre-screening and stronger models for judging, landing at roughly two cents per session. Most of the episode is process: build throwaway dashboards, cache and replay steps, read the actual prompts, and compare everything against a golden run made by Claude Code. They end on the unsolved part: how to tell when a memory has gone stale and how to feed human accept/reject decisions back into the pipeline.
Read the full summary
Recursive Self Improvement
Shapiro argues that recursive self-improvement is already happening, but not in the Skynet sense: it just means the share of AI progress (code, data, math) produced by AI itself is climbing fast — roughly 5% two years ago, ~30% now, and 50-80% expected next year. He points to OpenAI's and Google's recent batches of solutions to unsolved math problems (including Erdős problems) and rumors that Anthropic and Google are close to RSI as evidence. The second half argues the big downstream unlock is formal verification, which would let AI push into material science, medicine and other math-heavy fields, and that current capabilities are only at the 'sentences' stage of an emergence curve that goes much further.
Read the full summary
A walkthrough of the full lifecycle of shipping a production AI agent: a website concierge chatbot for a hotel business (modeled on a ~$5,000 freelance job) built with Google's Agent Development Kit, FastAPI, Gemini Flash and Postgres, deployed on Google Cloud Run. The process goes requirements doc → architecture doc → Linear tickets written as mini-specs → coding agents (Claude Code, Codex) doing the implementation → adversarial browser testing and LLM-as-judge evals → production concerns like backups, logging and metrics. The closing argument is that planning and architecture matter more than code now, because code is cheap to change and infrastructure decisions are not. The video is an acknowledged partnership with Google Cloud.
Read the full summary
A rundown of 23 habits that waste usage limits or degrade output quality on the newest Claude models, drawn from Anthropic's own guides, engineer comments, and power-user tips. The core themes: keep sessions scoped to one task, stop paying to re-read bloated conversations, stop defaulting to the biggest model and highest effort, and put guardrails around file edits, plugins, and MCP connectors. It ends with advanced fixes like cache-warming loops, session retention settings, manual compaction instructions, and automated model routing.
Read the full summary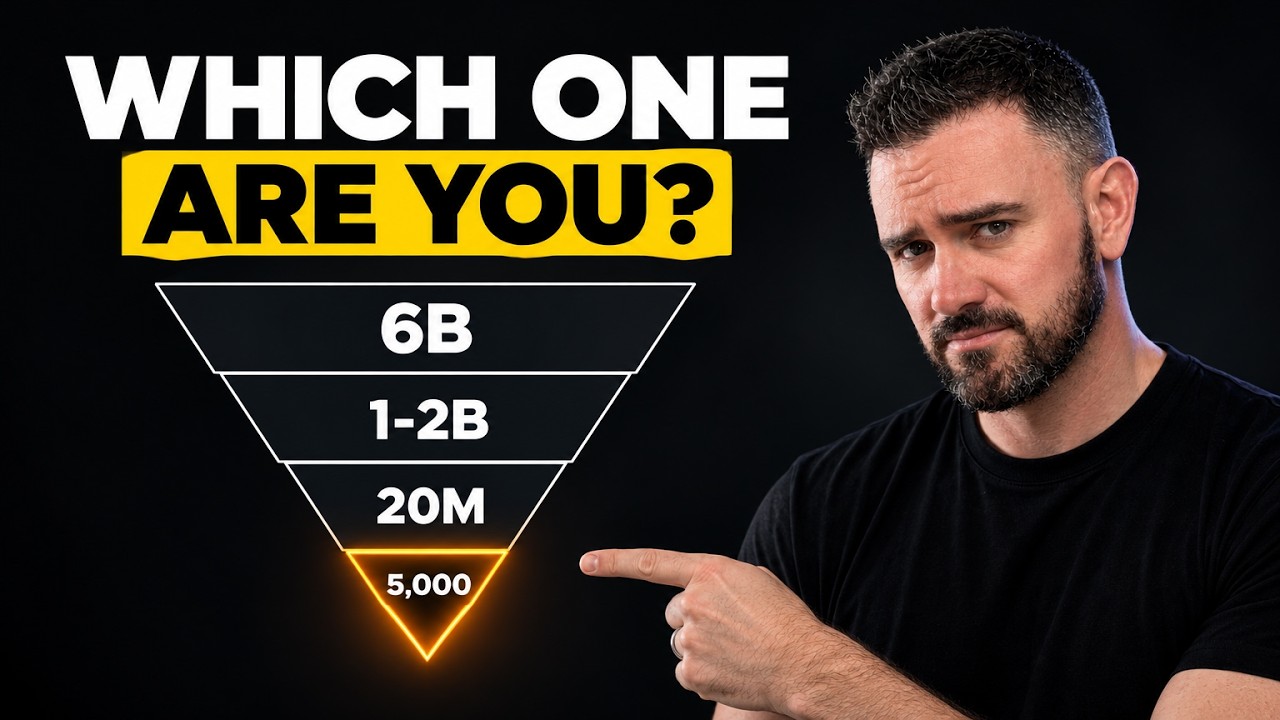
Rob Shocks breaks down Andrej Karpathy's post about a widening gap in how people use AI, which Karpathy frames as a four-layer funnel: ~6 billion people barely touched by AI, 1-2 billion casual chatbot users, ~20 million professionals using frontier models for coding and math, and ~5,000 people inside labs running agent swarms. The gap exists because of access, "jaggedness" (AI excels at verifiable digital tasks like code and math, lags at fuzzy ones like email), and the fact that impact scales with ambition. The host admits he thought he was in layer three but was mostly rebuilding existing SaaS apps faster, and argues most people — including experienced developers stuck in a 2024 mindset — are nowhere near ambitious enough with what they ask these models to do.
Read the full summary
Philipp Lackner shows a ~20,000-line Kotlin cloud file manager app built almost entirely by AI agents in two or three working days, then argues the only reason it works is that he has hand-written every one of those patterns hundreds of times before. His point: AI agents are now mandatory for a coding career, but reading AI-generated code teaches you almost nothing, so you should only delegate concepts you already understand deeply. His test is whether you could pass a spontaneous coding interview on a topic; if not, write that code yourself first.
Read the full summary
The video argues that a year of Claude Code advice is now outdated because the newer models (Opus 5/5.5) handle planning, self-checking and delegation on their own. Boris Cherny, who built plan mode, reportedly said on Hacker News that it's no longer useful; the replacement is a short brief with task, guardrails and a definition of done, then checking the output afterwards. The rest is a cleanup list: drop 'think hard' prompts for effort levels, turn done-criteria into runnable checks plus /goal loops, shrink CLAUDE.md to an index of pointers, build skills only from observed failures, replace shouty rules with hooks, and let Claude spin up its own subagents within caps.
Read the full summary
A developer named Brandon Thomas rebuilt seven Adobe Creative Cloud apps in Rust under the name Artcraft, open-sourced them, and made them run on Linux too. Fireship tried the Premiere clone (FilmCraft) to edit this very video and found it laggy and visually inferior, but says the real story is a separate viral tool, Reverse Engineer Anything (REA), which wraps Ghidra and AI agents to decompile stripped binaries, JVM bytecode, .NET assemblies, firmware, and container layers into readable pseudocode. The practical workflow is: decompile the one feature you want, hand the garbage pseudocode to a coding agent, and have it reimplement the feature in Rust so you can build a stripped-down clone of any paid app.
Read the full summary
OpenAI dumped 372 claimed math results on GitHub, many machine-verifiable in Lean but unexplained even by OpenAI's own mathematicians, while the company declined to publish the prompts its own advisory group asked for. The video ties that missing-receipts pattern to the AI debt market, where lenders are demanding to see books and OpenAI's annualized revenue just came in near $50 billion rather than the widely repeated $70 billion. It then covers an AI-assisted attack on at least nine South Korean banks by one person using an open-source tool, and proposes a three-layer accountability system modeled on anti-money-laundering rules.
Read the full summary
Docker Agent is an open-source Docker tool that lets you define an AI agent in a YAML file — model, instructions, tools — and run it with a single command, with Docker handling the agent loop (call model, run tools, feed results back). The video walks through a minimal agent, then a two-agent incident-debugging setup where one agent holds the logs and another queries it over the A2A protocol, and finishes with three agents playing a full battleship match. The pitch is that agents become versionable config you can push to a registry and expose as HTTP, MCP, or A2A services instead of hand-written Python boilerplate.
Read the full summary
REA ("reverse engineer anything") is a fast-rising GitHub repo — roughly 7–8k stars in a day — that packages an MCP server and CLI around existing reverse-engineering tools like Ghidra, Hopper and IDA Pro so a coding agent (Claude Code, Cursor, Codex) can investigate compiled binaries it has no source for. It doesn't recover original source code; it returns pseudo code, assembly, module maps, call paths and network activity with confidence levels and evidence. Rob demos it on a deliberately stripped and optimized "vault" app he built, and the agent finds the unlock logic among 242+ unnamed functions and writes a working code generator. His conclusion: reverse engineering was always possible, REA just removes the friction that acted as de facto protection, so code was never really the moat.
Read the full summary
Mario Zechner and Armin Ronacher talk through Pi Durable, a new release of the Pi agent harness that lets an agent survive a process crash and pick up exactly where it left off. Mario explains the design in detail: instead of event sourcing, everything in the harness is an "effect sandwich" (record intent → run the effect, ideally idempotently → persist the result), paired with a small versioned document store for application state that can be rewound alongside the conversation. The rest of the conversation covers where coding models have genuinely gotten better (anything with an oracle: tests, fuzzing, emulators, reverse engineering) versus where they haven't (architecture, because the act of designing software was never written down to train on), plus Earendil's plans to build non-coding-agent products and the unsolved security problems of extensible web UIs for agents.
Read the full summary
i use AI wrong (and you should too)
Lars Faye explains why he deliberately rejects the "AI-native, agents-first" workflow and instead treats models as a delegation layer rather than an abstraction layer: he states the intent, the model handles the how, and he still reads and owns the code. He delegates along four buckets — rote work, refactors, research, and reinforcement (self-taught tutorials) — and demos each with Zed as his editor and OpenCode's cheap open-weight models (GLM, Kimi, MiMo) on a $10/month plan. Examples include pulling formulas out of an Excel spreadsheet into PHP, swapping a browser alert for a custom modal in a years-old codebase, and using a model as an interactive Laravel tutor. His closing point: code generation solved the typing problem, not the thinking problem.
Read the full summary
Dexter Horthy (CEO of Human Layer) argues that although coding agents got much better at solving problems in 2026, they did not get better at keeping codebases maintainable, so the "lights-off" software factory where nobody reads the code doesn't work yet. He backs this with SlopCodeBench, a University of Wisconsin benchmark that reveals models' code degrades as features accumulate (GPT-5.5 scored 14.8%), plus industry data showing code review quality down and incidents/bugs per PR up. He then lays out ~9 practices for an agentic "software factory" — plan before building, align visually, give agents back pressure, feed user feedback and pager alerts straight into PRs — and sketches the buy-or-build layers (compute, dev environment, harness, control plane) that Human Layer is targeting.
Read the full summary
Turbopuffer, the vector search vendor behind Cursor, Notion, and Anthropic, is demoting the vector index in its v3 engine from the center of the system to just one index among keyword search and filters. The video walks through the three alternatives competing for that center slot s agentic search loops, live MCP connectors, and pre-compiled knowledge files s with benchmark numbers and costs for each. The conclusion: vector DBs aren't dead, just demoted, and for most new builds the default should be an agent with cheap search tools, keyword search first.
Read the full summary
Fireship recaps a chaotic week in the open-weight model race: Mistral released Mistral Large 4, a trillion-parameter mixture-of-experts model with a million-token context window, one day after US startup Reflection AI finally shipped Beam, a 501B-parameter model trained on $6.3 billion worth of GPUs that Mistral promptly out-benchmarked. Meanwhile Moonshot AI closed a round at a $50 billion valuation while its Kimi K3 model already does what both Western labs are chasing. The underlying argument: privacy, surveillance, and sovereignty are why every government wants an open model of its own.
Read the full summary
The big lie about AI coding
A rant against what the host calls the "Markdown Industrial Complex" influencers packaging prompt files, "skills," and agent stacks as proprietary AI-coding methodology. His claim: there is no special skill in AI coding beyond picking a reasonable effort level and putting in long hours, and the people shipping huge volumes of PRs are just working 10-12 hour days. He argues the tricks people distribute are usually AI-generated themselves, address problems newer models already solved, and that real capability gains come from labs post-training the models, not from your prompt folder.
Read the full summary
The creator uses an anecdote from Bill Bryson's A Short History of Nearly Everything — about an amateur astronomer who hunts supernovas by eye rather than by computer — as an analogy for developers who still write code by hand in the AI era. His point: AI is a tool that can be used in different doses, and if you genuinely enjoy writing code, there's no obligation to hand it over to Copilot. He also notes the astronomer's line that he 'still beats them sometimes,' suggesting manual work occasionally catches what automation misses.
Read the full summary
Anthropic shipped "mods" for Claude Code (released Oct 1), small add-ons that change how Claude Code itself looks and works by listening to events and watching, modifying, or handling them. The video walks through nine mods worth trying — Savvy Progress, Claude Skins, You Should Know, File Tree, Cache Tax, Blast Radius, Reflect, Terminal Browser and Replay Theater — and explains how mods differ from skills and MCP connectors. Building one is just a matter of describing it to Claude, which has a built-in "plugin authoring" skill; mods are temporary by default until you ask Claude to save them as an installed plugin.
Read the full summary
Rob compares three popular Claude/agent skill packs: Addy Osmani's newly open-sourced set (25 skills plus four reviewer personas, built around a six-stage define/plan/build/verify/review/ship lifecycle), Matt Pocock's small composable skills focused on upfront alignment, and Lauren Tan's PStack focused on verification and evidence. His conclusion: Osmani's pack is the most team- and enterprise-friendly because it follows the conventional SDLC with no new metaphors to learn, Pocock's is best for fuzzy design problems, and PStack is best for gnarly bugs, migrations and long autonomous runs. The bigger argument is that you shouldn't install everything everywhere — ceremony should match the stakes, and extra skills bloat context and auto-trigger when you don't want them.
Read the full summary
Stop Using AI For This
Kyle Cook argues that developers are wrapping deterministic logic in English prompts and AI "skills" when they should just write a program. He uses Gary Tan's G stack skills as an example: a markdown-to-PDF skill that is essentially code and if-statements written out in prose, fed into a non-deterministic machine. His fix is to generate a CLI tool or small scripts once, let the AI call them, and isolate AI to the genuinely ambiguous step "- like transcription in his own video editor "- so one hallucination doesn't break an entire chain.
Read the full summary
Kent Beck argues that the claim "AI is better at coding than humans" is nonsense: LLMs (which he calls "the genie") produce plausible code that often doesn't actually work, so programmers and buyers now need an adversarial posture toward AI-generated software. His central model is a tradeoff between features (visible progress) and futures (optionality to change), and he says the real skill is pausing between features to restore optionality rather than racing to the zero-option mess that AI now lets you reach in a week instead of a decade. He dismisses spec-driven development as rebranded waterfall, explains why formal methods still leave a gap, and closes by warning that lines of code and PR counts measure effort and output, never mission.
Read the full summary
Syntax Weekly covers a dense week of releases: prolific open-source maintainers (Sindre Sorhus, SWC, Hono, Ladybird) are turning off external pull requests because AI-generated "slop" PRs have made free code worthless and review expensive. Pi shipped 1.0 with built-in MCP and code mode, plus a separate Pi Durable harness for resumable, long-running agents, and Turso is joining Supabase. The rest is a whirlwind: SvelteKit 3, Effect 4.0, Alchemy infrastructure-as-code, Cloudflare's new config.ts and its own decision model, OpenAI DevDay announcements, NVIDIA's Lyra 2.0 world model, game decompilation/recompilation, a TC39 composites proposal, and a pigeon-delivered IP packet up for auction at Christie's.
Read the full summary
Owain Lewis walks through an autonomous "AI SRE" agent he built with the Claude Agents SDK: production alerts flow into a queue, the agent investigates logs, metrics and deployment history, writes its findings to a database, and surfaces them in a custom web console where an operator can approve actions like a rollback. He demos it detecting a deliberately broken deploy (payment config error causing 500s), recommending and executing a rollback, then a second case of a slow-but-working deployment diagnosed via chat. His main caveat: these agents are superhuman at digging through data but routinely over-index on single signals and jump to conclusions, so critical actions should stay human-in-the-loop.
Read the full summary
Iconographer Jonathan Pageau uses the Grail legend to argue that our culture celebrates technological discovery while skipping the question that actually matters: whom does the technology serve? He frames the AI race as a modern Moloch trap, where competitive fear (losing to China, losing market position) drives us to sacrifice jobs, energy, children's minds and our grip on reality. Since no system-level fix exists, he argues the only real answer is personal: cultivate memory, skill, virtue and faith inside yourself so you stay master of the machine rather than its vassal.
Read the full summary
Matt Pocock interviews Poteto, creator of the pstack skill library and an engineer at Cursor (now SpaceX AI, previously Meta's React team), about how he shipped ~2,500 PRs to production in a month. His argument: the agent isn't the bottleneck anymore — your environment and your ability to transfer intent are. The practical core is verification (giving agents hands and eyes so they can close their own loop), heavily constrained codebases where bad code is hard to write, and connecting an "outer loop" of external context (Slack, X, email, Linear) to an "inner loop" of coordinator agents that spawn sub-agents. He now lets agents merge their own PRs overnight and reviews by sampling commit history in the morning.
Read the full summary
Jo Van Eyck walks through a working "software factory" he built: GitHub issues feed a chief-of-staff agent that spawns a fleet of workers and reviewers, which plan, code, self-review, and open a PR with evidence attached. His main argument is that the factory tooling itself is the easy part — the real prerequisites are a codebase that can run in a container, a type system, a fast hexagonally-designed test suite, custom lint rules, and static analysis. He advocates a "dim factory" rather than a fully dark one: skip most PR reviews, but periodically sweep the code manually to check that core primitives haven't been corrupted.
Read the full summary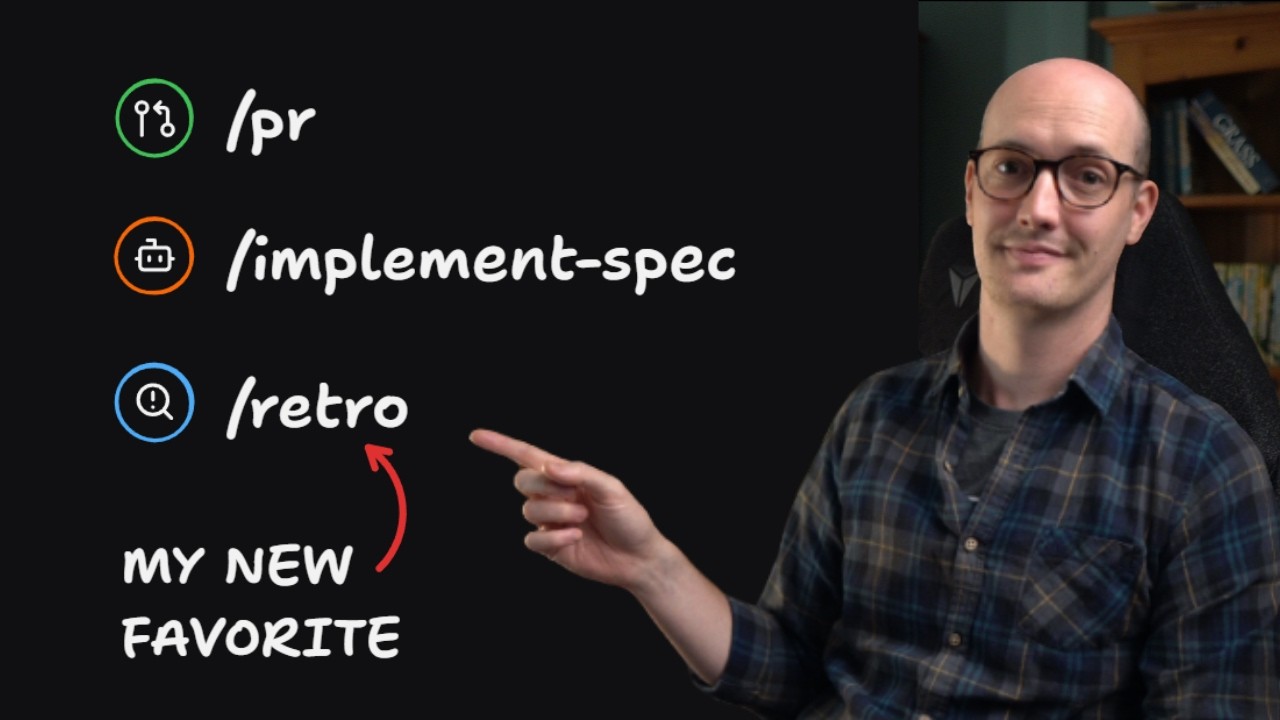
Matt Pocock walks through version 1.3 of his skills repo, which adds three skills: /implement-spec, /pr, and /retro. implement-spec orchestrates a whole spec's tickets through sub-agents (a middle ground between manually babysitting each ticket and writing a deterministic script loop), /pr enforces a PR body template with a visual summary, before/after evidence, merge danger and blast radius, and /retro reads your actual past agent sessions and suggests repo and agent improvements. He also notes a breaking rename: domain modeling now writes to glossary.md instead of context.md, which many other skills depend on.
Read the full summary
The end of the app era: What comes next?
Nate Jones argues that as agents take over the "information processing" part of jobs, the software application interface stops being where value lives — and that breaks how companies buy and sell SaaS. He walks through how Meta (Muse), Salesforce (COA + agent control plane), Microsoft (Autopilot/Copilot), the labs, DoorDash (text ordering + MCP), Crust Data and Workday are each positioning across three layers: data, application/workflow, and agentic. His practical advice: individuals should stop hoarding their personal AI tricks and talk openly about how they work, because leadership will swap vendors without knowing what productivity they're destroying.
Read the full summary
Laurie Voss argues that AI agents have made code generation cheap while human review has stayed the same speed, creating the real bottleneck: one study of 100,000+ GitHub developers found agent users wrote 741% more code but shipped only 30% more software. He walks through the evidence on whether automated review can replace humans — METR's maintainer study, Cognition's Frontier Code benchmark, GitHub/Cursor's production reviewers, and the Bun and OpenAI no-human experiments — and concludes review hasn't died, it's been relocated. His practical advice: stop reviewing individual PRs and spend your human judgment building the review harness, rubrics, and evals that review for you.
Read the full summary
Microsoft is shipping Autopilot (earlier called Scout), an agent built on OpenClaw's open-source tech — the same agent Satya Nadella compared to a virus back in February — now packaged with an auditable identity, admin controls and a support contract. Nate Jones argues this matters less because the model is smart and more because of distribution and data: Microsoft has 450M+ paid M365 commercial seats and 30M+ paid Copilot seats, so for a lot of workers Autopilot will simply be the AI they're allowed to use. The bulk of the video is five habits for getting value out of any agent — define what good looks like, supply and verify context, make good assignments recur, match reasoning to difficulty, and close the learning loop.
Read the full summary
Claude Ultracode is super intelligence.
The host reports that Claude Opus 5.5 running at "Ultra Code" effort level implemented a 2,700-line spec for his app "Enjoy" end to end in roughly seven hours, something that failed catastrophically when he tried similar work in March. He argues the model's self-spawned adversarial reviewers, heavy test coverage, and honest self-reporting mean agentic code is now trustworthy without line-by-line human review. He concludes that CI, not code review, is the real bottleneck, and warns engineers who insist on manual review that they may be hurting their careers.
Read the full summary
Anthropic updated its skills best-practice guide, and the new rules largely contradict how people built skills earlier this year. The biggest one: Claude previews long reference files with `head -100`, so anything important below line 100 in a file without a contents list may never be read. The other changes cover matching instruction detail to how fragile a task is, testing skills on every model you'll run them with, keeping references one level deep, adding checklists and self-validation loops, and spelling out dependencies so skills work on someone else's machine.
Read the full summary
Matt Pocock argues that AI agents have turned the PR review queue into a firehose, and the fix is three layered "brakes": cheap deterministic checks, an automated reviewer running in its own sub-agent, and a much lighter human review. His core unintuitive advice is to keep coding standards out of the implementer agent (which is already overloaded with exploring, editing, and debugging) and put them in a coding-standards.md file that only a review agent reads, and to have that reviewer commit fixes rather than leave comments for humans. He also introduces new skills: a PR skill that labels every PR as a one-way or two-way door with a blast radius, and a "retro" skill that mines past sessions and reviews to generate new checks and standards so each cycle compounds.
Read the full summary